

Context engineering with AI ontologies
Trust is the number one blocker of enterprise AI, and governed context is the unlock. Every output gets grounded in the truth of your business, with a central ontology that learns which dashboards people actually trust, or which team owns a process.
Ready to shorten the path from question to decision?
Clients who trust us


What ontology engineering can do
Gartner predicts that by 2027, organizations that prioritize semantics in AI-ready data could see up to 80% better agentic AI accuracy.
77%
more reliable outputs
more reliable outputs
60%
lower cost per call
lower cost per call
100%
traceable answers
traceable answers
How to make it work
Start at one end, scale across

The architecture, layer by layer
In our clients' words

“Hiflylabs feels like an extension of our own team. They combine stellar engineering with a genuine commitment to our business, consistently delivering long-term solutions that provide real value to our stakeholders.”
Maxime Lagresle
-Senior Director of Data, Veronica Beard


Align with your team
A full AI ontology is an organizational project. Best scope one domain first, prove ROI, and scale from there.
To start, your team needs to align on: agreed definitions within that one, clean domain, their governed, consolidated data sources, and a set of questions for evaluating accuracy (cca. 50 questions your team would ask the AI).
Go deeper on AI ontologies


Entry point for ontology engineering
This one-pager explains our ontology engineering services concisely. For the best reading experience, we recommend viewing it on mobile devices.


FAQ
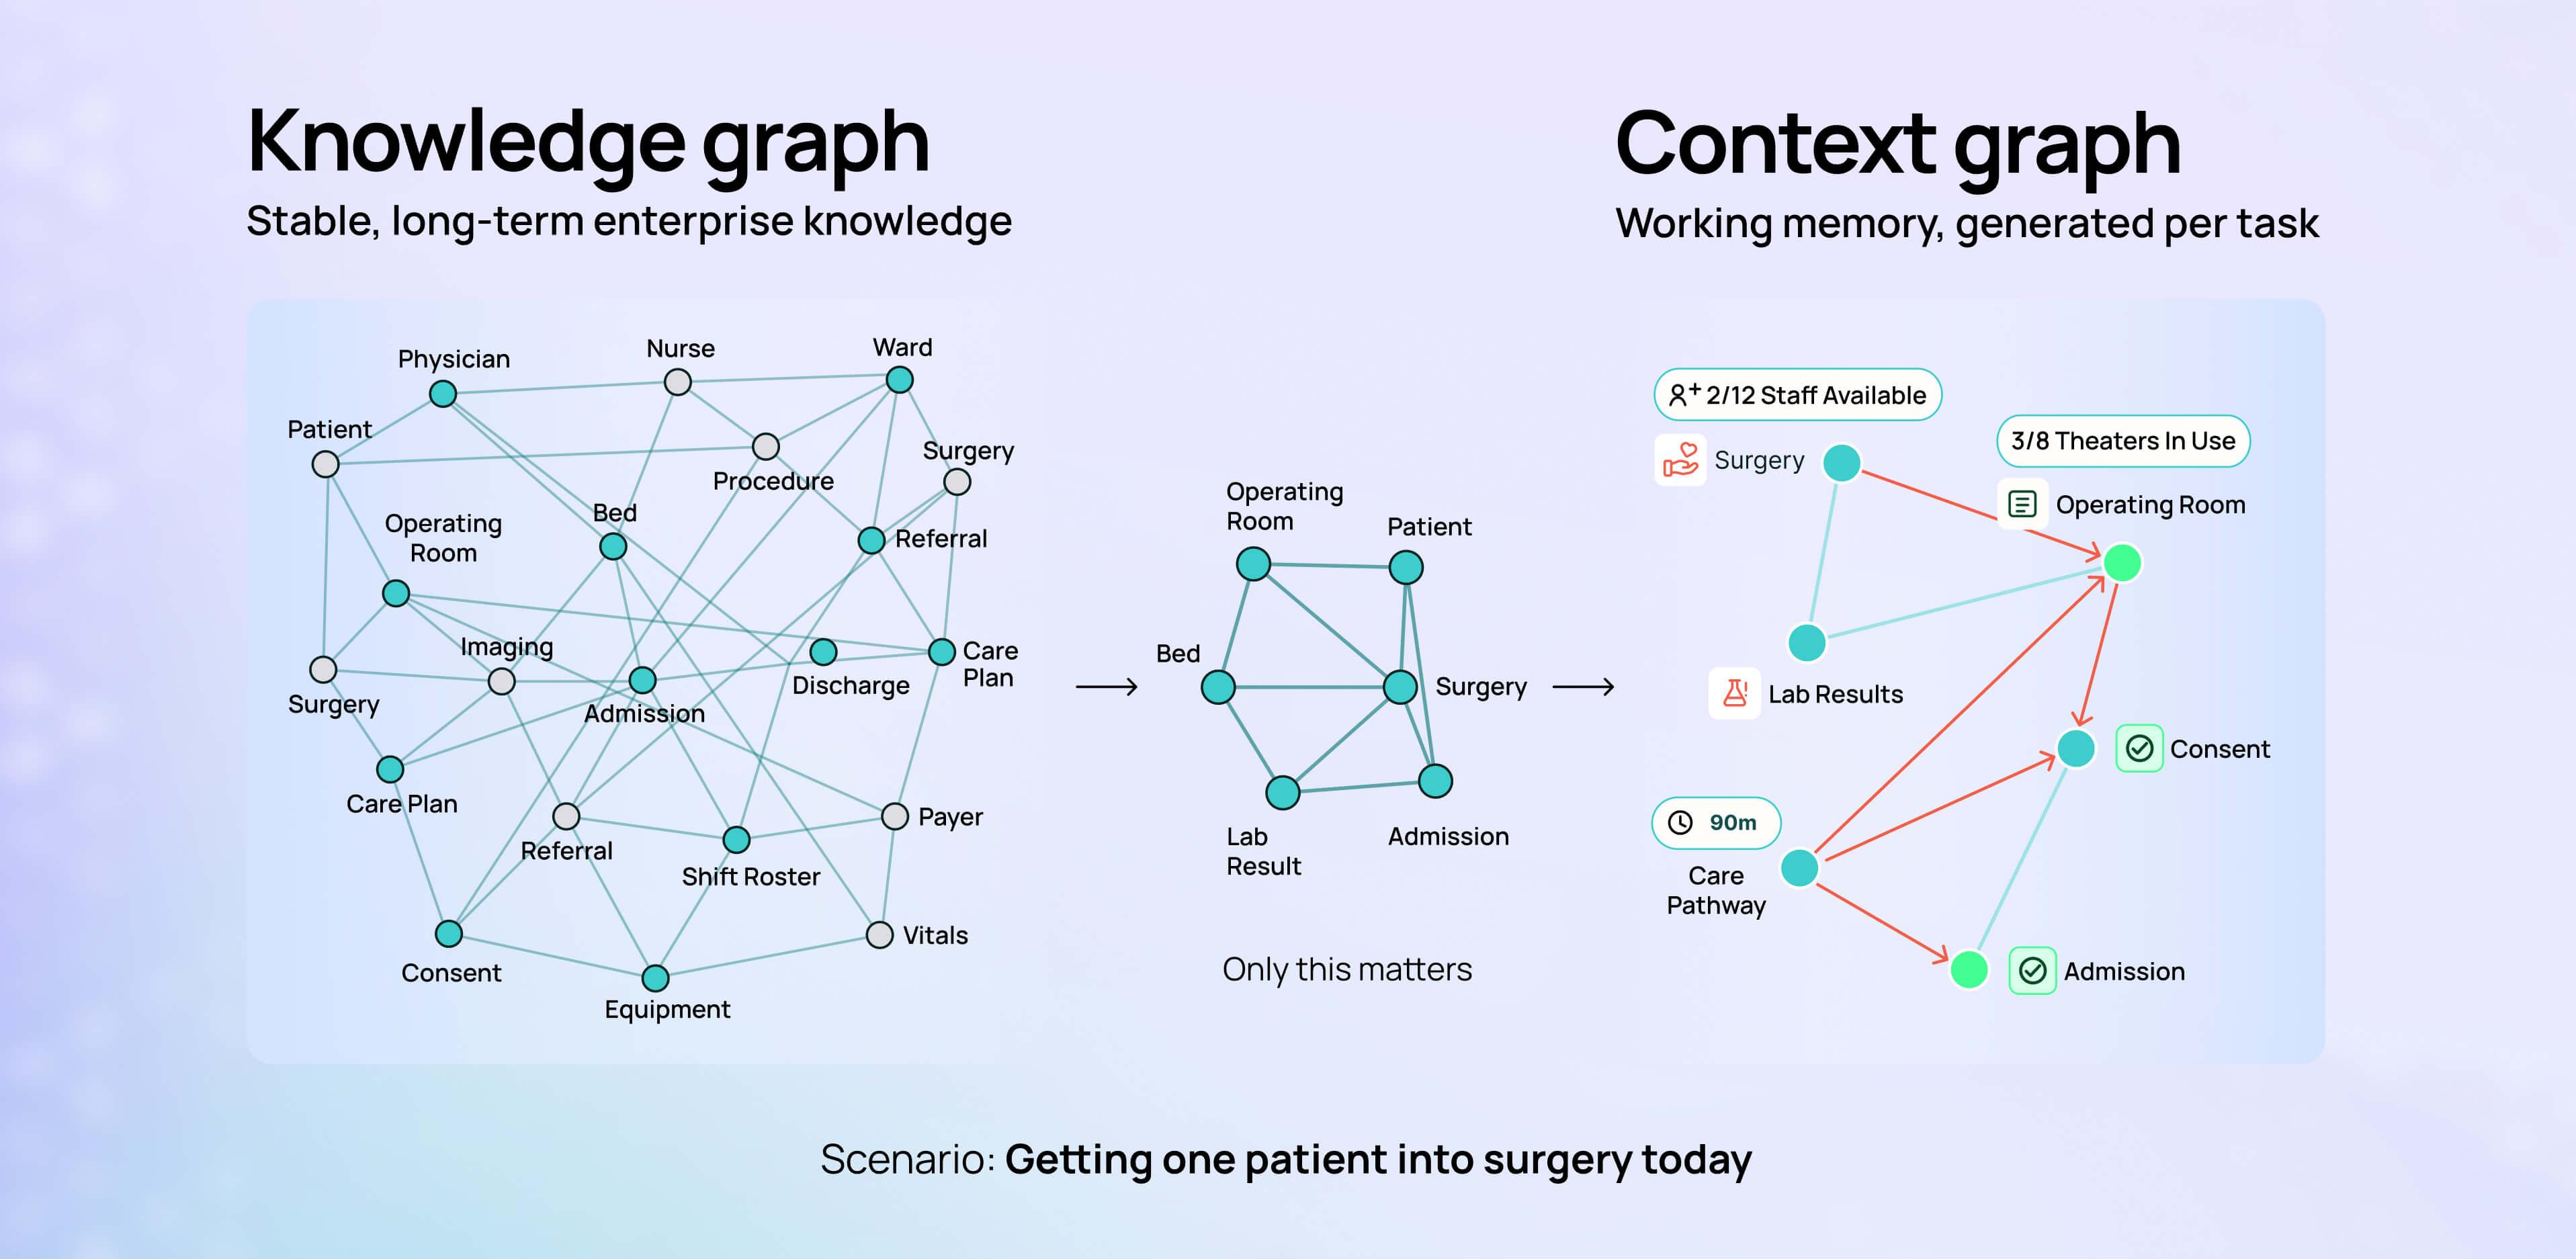
Ontology engineering means building a formal, machine-readable model of your business: its entities, relationships, rules and actions. It’s a concept related to taxonomies and semantic layers, with key differences. BI semantic layers act as vocabularies translating between business terms and data warehouse tables for reporting. A taxonomy classifies entities into categories. An ontology adds relationships and rules. The performance of AI agents is enhanced when you have those nuances spelled out, which makes ontologies the most useful form of context engineering for AI.
Start at one end of the data pipeline: either your data foundations, or one high-value use case that needs context. Pick one department. Choose a stakeholder owning glossary definitions, process descriptions, and test questions. If your entity resolution accuracy is above 90%, and your AI outputs are better with the ontology than without, then you know it’s working as intended. Then, you can start thinking about expanding it horizontally in the organization.
Using the pre-existing ontology solutions of major data intelligence platform providers can shorten the timeline to a matter of weeks. If your company has not consolidated their relevant data sources on a single platform yet, then building even a single-domain ontology from scratch can take around 2-3 months. A company-wide ontology, one with robust AI automation on top, takes months to quarters (and aligning every department and stakeholder will take longer than the build itself). Lighter context layers can go live much faster. In existing AI products, clearing up definitions is most of the work.
Every definition has an owner and a review cadence. Changes get a version and an effective date, and tests should rerun before release. Each AI answer or action has a record of the version it used. For small adjustments and automated pipelines, feedback loops update the ontology from trusted sources. But when a whole process changes, the schema should change with it, which will require manual adjustment from the owner.
If your data and governance already live in Databricks, Genie Ontology (with OntoRank) makes the most sense. On Snowflake, Business Ontology (with Cortex Sense) brings similar value. Either way, the real work is preparing what they learn from: federated sources, permissions, metric views, glossary and defined domains. For most enterprises, a fully custom ontology might be too complex and hard to maintain, but could fit better if you need full control, or aim to avoid any kind of vendor lock-in.
Sure, LLMs draft well from data and documents. But ontology engineering is not the challenging part. The organization has to be able to define its own processes. Real people need to sign off on contested definitions. Your team needs a project sponsor, domain owners who can define things and settle disputes, and data platform experts who set up access rights and data governance. You can outsource building the data pipelines, getting the platform in order, or AI automations. But beware that most ontology projects stall on corporate politics, not engineering. An advisor who can help with organizational challenges can sometimes be more valuable than an engineer.
Run the same 50 or so real-life questions with and without the ontology. Compare the reliability of the outputs. If accuracy is above 90% (or better than without the ontology), hallucinations are down 55-99%, then you know it’s working. Answers also become auditable, with lineage and definitions visible at any time. Put together, this can mean a 5x productivity increase in AI-heavy workflows and half the overall AI spend.